 English
 EN
 FRENCH
 繁体中文




What Is Data Parsing? How It Works in Web Scraping
Learn what data parsing is, how it works in web scraping, and how businesses extract structured data for market research, price monitoring, and SEO analysis.
Websites contain valuable information, from product prices and customer reviews to search results and market trends. However, raw web content is often difficult to analyze directly. Data parsing turns that information into structured data that can be stored, compared, and analyzed more efficiently.
In web scraping, parsing is the step that transforms collected webpage content into useful information. It plays an important role in market research, price monitoring, SEO analysis, and ad verification.
What Is Data Parsing?
Data parsing is the process of reading raw information, identifying relevant elements, and converting them into an organized format.
For example, an e-commerce page may contain a product name, price, rating, and availability status. A parser identifies these elements and separates them into clear data fields for further analysis.
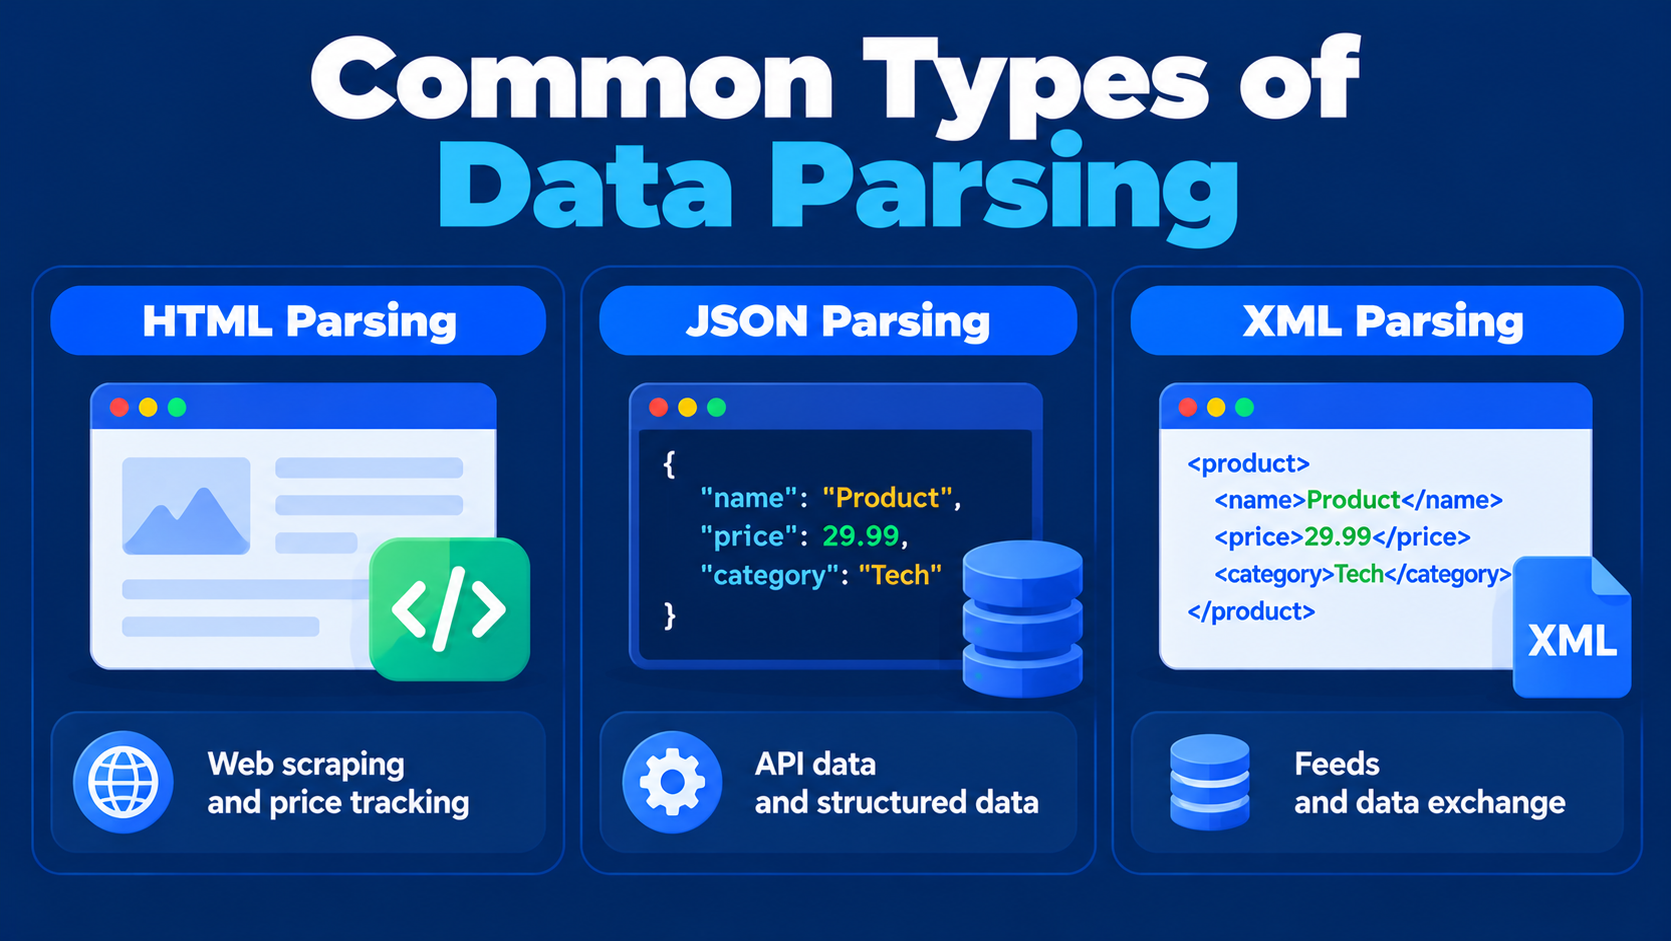
Instead of processing an entire webpage, businesses can focus only on the information they actually need. HTML, JSON, and XML are among the most common formats used in data parsing.
How Does Data Parsing Work?
A typical parsing process includes four basic steps.
- Collect the data – Retrieve content from a website, API, or another source.
- Identify relevant information – Find elements such as prices, titles, ratings, or links.
- Extract the values – Separate useful information from the rest of the content.
- Organize the results – Store the data in a format that can be easily analyzed.
For example, an e-commerce monitoring system may collect product pages, identify prices and stock information, and organize the results for comparison. This makes it easier to track changes across large product catalogs.
Data Parsing vs Web Scraping
Data parsing and web scraping are closely related, but they serve different purposes.
Web scraping collects website content, while data parsing organizes the information within that content.
A scraper may retrieve a product page, while a parser identifies the product name, price, rating, and availability. Scraping provides the source information, and parsing makes it useful for analysis.
Common Types of Data Parsing
HTML Parsing
HTML parsing extracts information from webpage elements such as headings, links, product details, and prices. It is commonly used in web scraping, competitor monitoring, and price tracking.
JSON Parsing
JSON parsing processes structured information often returned by APIs and modern web applications. Because the data is already organized into fields, it is generally easier to process.
XML Parsing
XML parsing reads structured documents commonly used in feeds, business systems, and data exchanges. The right method depends on the source and format of the information being collected.
How Residential Proxies Support Web Scraping
Parsing can only begin after the required website content has been collected. For large-scale or location-specific scraping projects, reliable access to web data is therefore an important part of the process.
Swiftproxy Residential Proxies provide residential IP addresses across different locations. They can support web scraping tasks that require geographic targeting, IP diversity, or access to region-specific public content.
Proxy rotation distributes requests across different residential IPs, which can be useful for market research, price monitoring, and large-scale data collection.
For workflows that require a consistent IP address, Swiftproxy Static Residential Proxies are better suited to longer sessions where connection stability is important.
Residential proxies do not perform parsing themselves. They support the data collection stage, while parsing tools organize the retrieved information afterward.
How Businesses Use Parsed Web Data
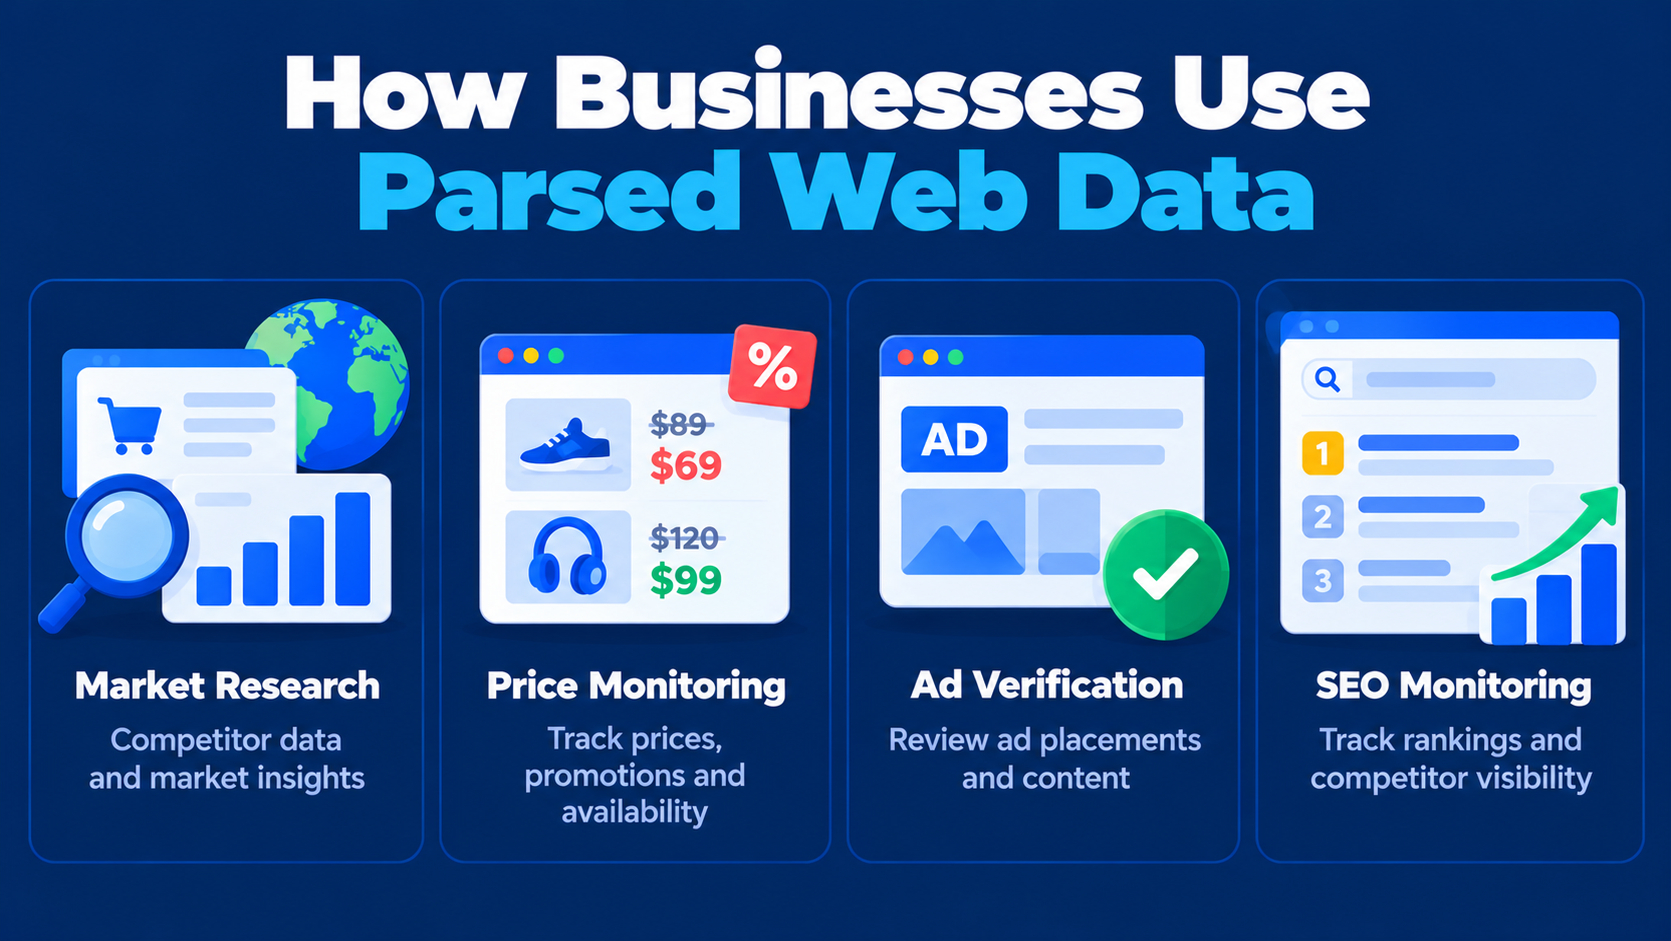
Market Research
Businesses can collect and organize competitor prices, product information, reviews, and market data. Structured information makes it easier to compare competitors and identify changes across different markets.
Price Monitoring
E-commerce companies can track prices, promotions, and product availability. Parsed data allows these changes to be compared over time.
Ad Verification
Advertisers can review ad placements, landing pages, and displayed content. Residential proxies can also support verification from different geographic locations.
SEO Monitoring
SEO teams can organize search result information to track rankings, competitor visibility, and regional search performance.
Best Practices for Reliable Data Parsing
Reliable data parsing depends on clear extraction rules and consistent source information.
- Use suitable parsing tools for the type of data being processed.
- Validate important fields before storing the results.
- Monitor websites for layout or content changes.
- Handle missing, duplicate, or incorrect values.
- Choose rotating or static proxies based on the scraping workflow.
- Follow applicable website policies and reasonable request rates.
These practices help improve data quality and make web scraping systems easier to maintain.
Conclusion
Data parsing turns raw web content into organized information that businesses can use for research, monitoring, and analysis. Combined with web scraping, it supports applications such as market research, price monitoring, SEO tracking, and ad verification.
For web data collection across different regions, Swiftproxy offers residential proxies for flexible IP rotation and static residential proxies for workflows that require stable connections.
Frequently Asked Questions
What is data parsing?
Data parsing converts raw information into an organized format that software can process, store, and analyze.
Is data parsing the same as web scraping?
No. Web scraping collects website content, while data parsing extracts and organizes useful information from that content.
Why are residential proxies used for web scraping?
Residential proxies provide residential IP addresses and geographic flexibility. They can support data collection tasks that require regional access or IP diversity.
What is proxy rotation?
Proxy rotation changes the IP address used for requests according to a defined strategy. It is commonly used in larger web scraping projects.
When should static residential proxies be used?
Static residential proxies are useful when a workflow requires the same IP address across multiple requests or longer sessions.
About the author
 Top-tier residential proxy solutions
 {{item.title}}
Related articles

 433


- Please provide your account number, or email address.
- Provide videos or screenshots, and simply describe the problems you are facing.
- Our staff will reply to your message within 24 hours.