 English
 EN
 FRENCH
 繁体中文




How CaaS and Residential Proxies Scale Web Scraping
Learn how combining Containers as a Service (CaaS) with residential proxies enables scalable, distributed, and geo-targeted web scraping pipelines.
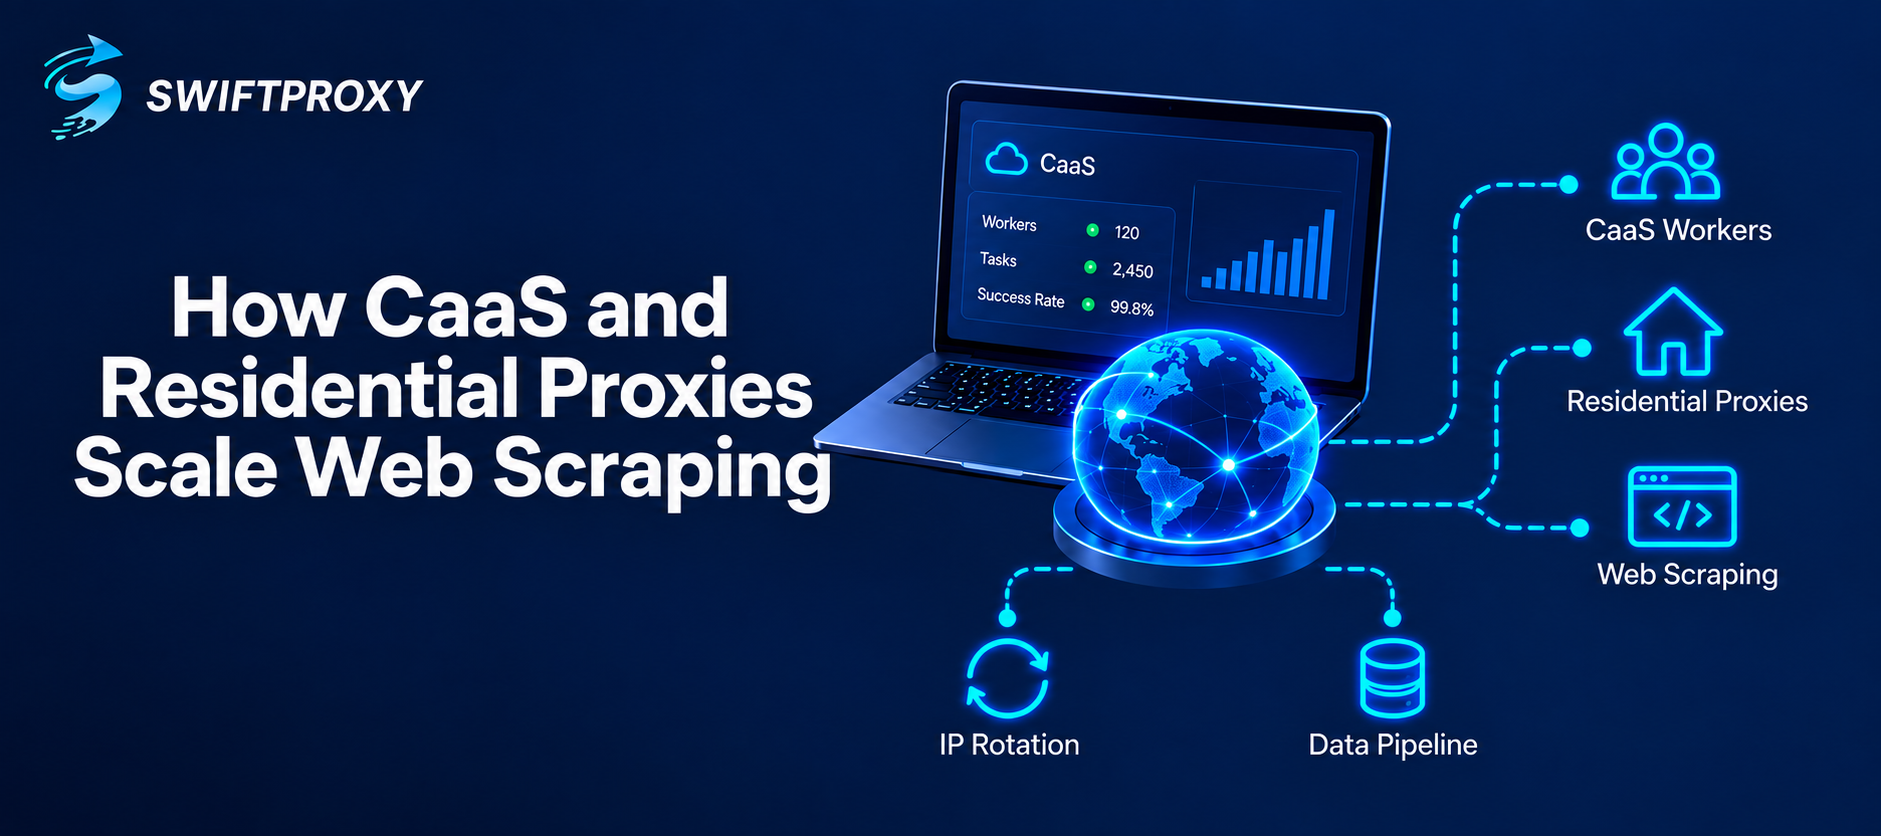
Scaling web scraping is not just about increasing server capacity. As projects grow, teams also need a reliable way to manage large volumes of web requests across different locations and sessions.
Containers as a Service (CaaS) makes it easier to deploy and scale scraping workloads, while residential proxies provide the network flexibility needed for distributed web access.
Combined, they offer a practical foundation for large-scale web scraping, market research, ad verification, SEO monitoring, and AI-driven data workflows.
What Is CaaS
CaaS is a cloud model for deploying and managing containerized applications.
Instead of running an entire scraping system on one server, teams can package scraping logic into containers and distribute jobs across multiple workers. Capacity can then expand or shrink as demand changes.
This approach works well for large URL lists, recurring monitoring tasks, and parallel data collection.
However, adding more containers does not automatically improve access to target websites.
Why the Proxy Layer Matters
More scraping workers can increase pressure on a limited set of outbound IPs, leading to rate limits, CAPTCHAs, or failed requests.
SwiftProxy Residential Proxies help distribute traffic across rotating or sticky residential IPs, giving CaaS workloads more flexible and reliable web access.
Task Queue → CaaS Workers → Residential Proxies → Public Websites → Data Processing
Proxy Rotation for Distributed Tasks
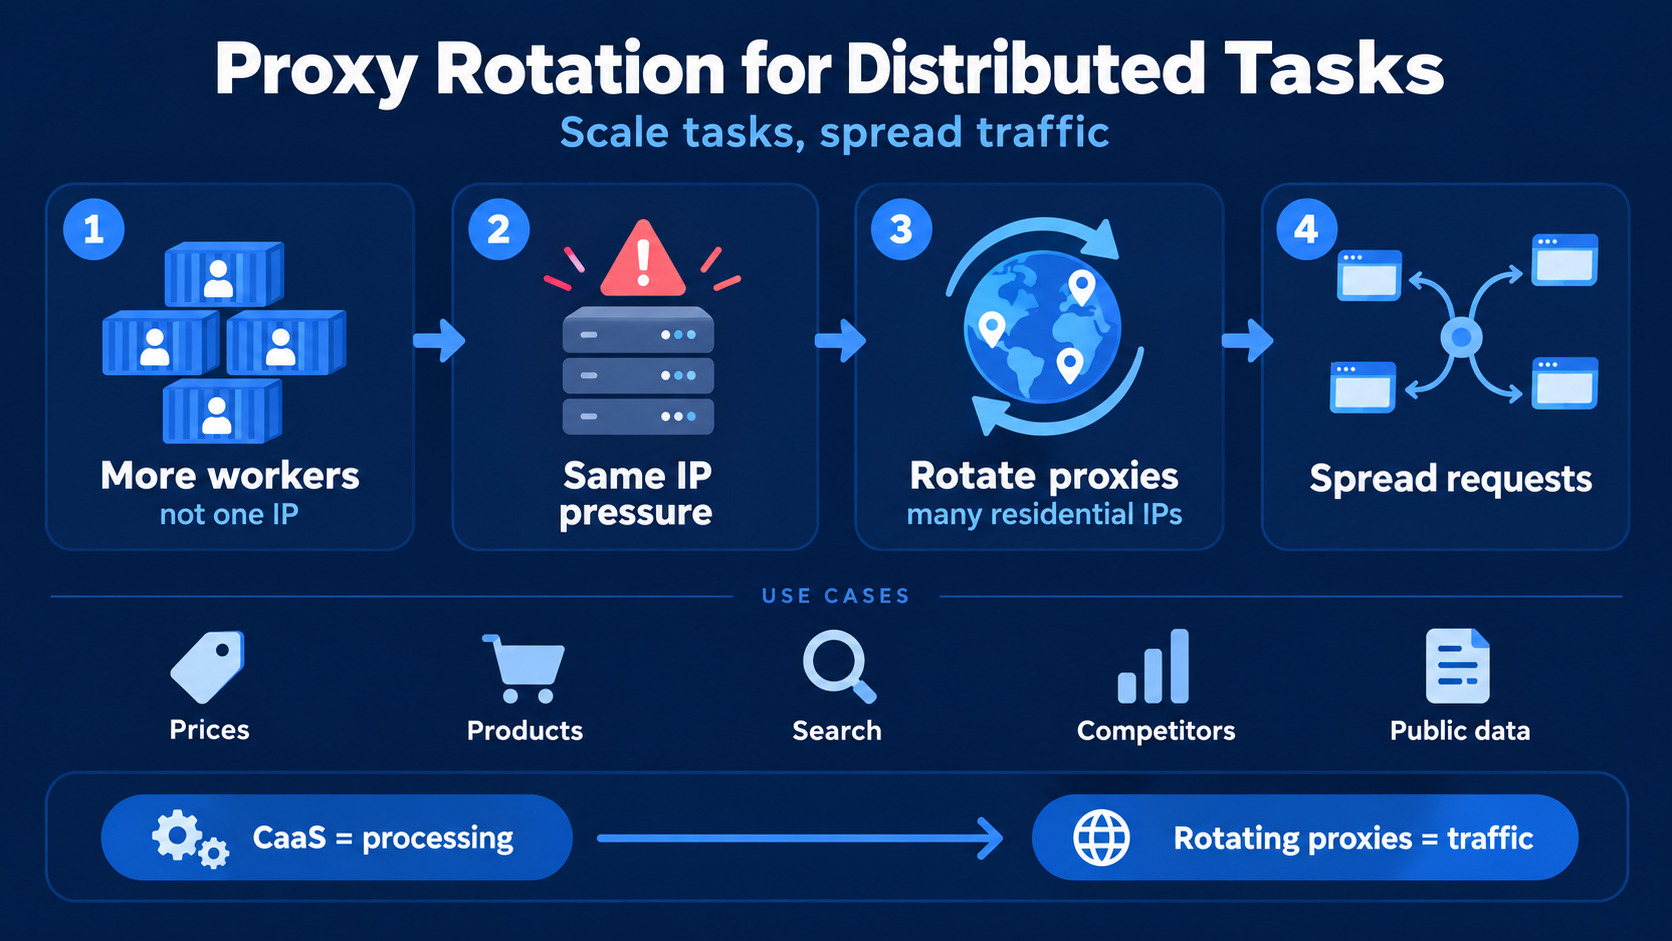
As scraping workloads expand, IP management becomes increasingly important.
If every worker repeatedly uses the same IP, deploying additional containers may increase pressure on that address rather than improve throughput.
Proxy rotation distributes requests across multiple residential IPs.
This works well for independent tasks such as:
- Price monitoring
- Product data collection
- Search result tracking
- Competitor research
- Large-scale public data extraction
For these workloads, CaaS distributes processing while rotating proxies distribute network traffic.
When Static Residential Proxies Make More Sense
Some workflows require a consistent IP across multiple steps. In these cases, SwiftProxy Static Residential Proxies can help maintain session continuity and a stable browsing environment.
Rotating proxies are better for large volumes of independent requests, while static residential proxies are more suitable for persistent, session-based tasks.
Building a Scalable Web Scraping Pipeline
A well-designed scraping system separates responsibilities.
CaaS workers execute jobs. The proxy layer manages network access. Downstream services clean, process, and store the collected data.
A product intelligence platform could divide thousands of product URLs across multiple containers. Each worker retrieves assigned pages through residential proxies, while separate services normalize prices, inventory data, and product details.
SwiftProxy Web Scraping Proxies can serve as the access layer for these distributed public web data workflows.
This modular structure makes the system easier to scale, monitor, and maintain.
Market Research With Localized Access
Market research often depends on understanding what users see in different locations.
Websites may vary prices, product availability, promotions, search results, or content according to the visitor's region.
CaaS workers can divide research tasks by market, while residential proxies provide location-specific access.
This gives businesses a clearer view of regional conditions and can support competitor monitoring, price intelligence, and product research.
Ad Verification Across Regions
Advertising is also location-sensitive.
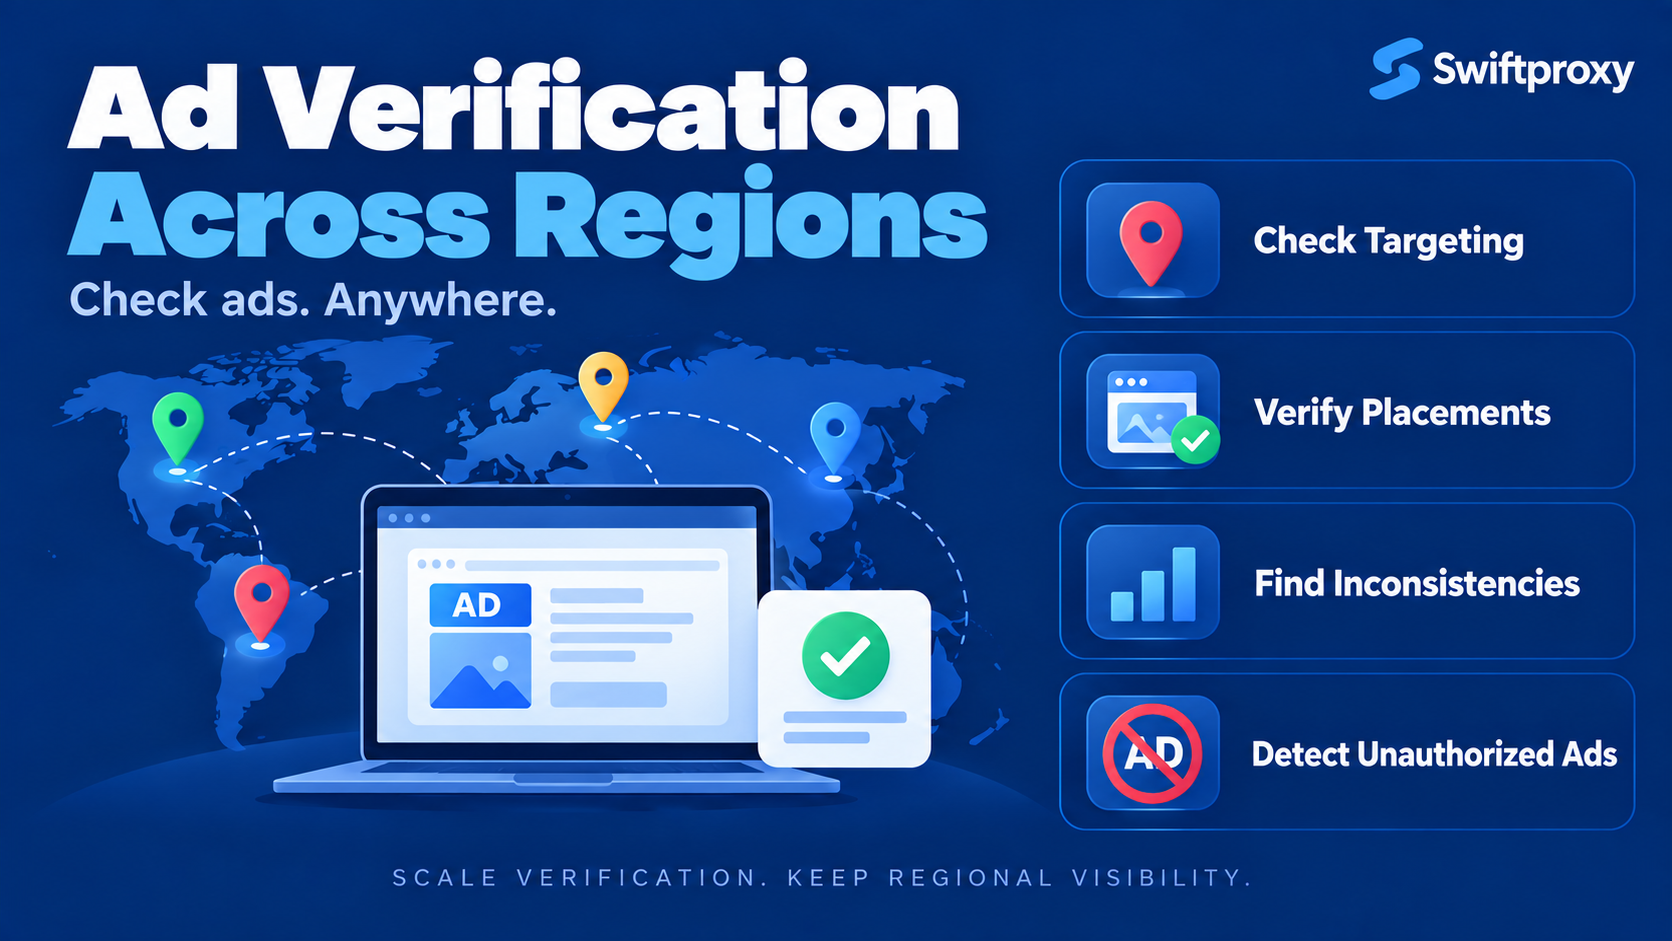
Brands may need to confirm whether campaigns appear in the intended regions, whether landing pages load correctly, or whether ads are displayed consistently across markets.
Containerized workers can perform these checks in parallel. Residential proxies provide the regional IP context required to observe localized ad delivery.
This can help identify:
- Incorrect geographic targeting
- Missing placements
- Campaign inconsistencies
- Unauthorized ad placements
The combination allows businesses to scale verification without losing regional visibility.
Supporting AI Data Workflows
AI applications often rely on fresh web data for research, monitoring, and analysis. Containerized workers can collect and process this information at scale, while residential proxies provide flexible access to public websites.
AI Application → Data Queue → CaaS Workers → Residential Proxies → Public Web
This structure keeps data collection scalable and easier to manage as AI workloads grow.
Design Compute and Proxy Scaling Together
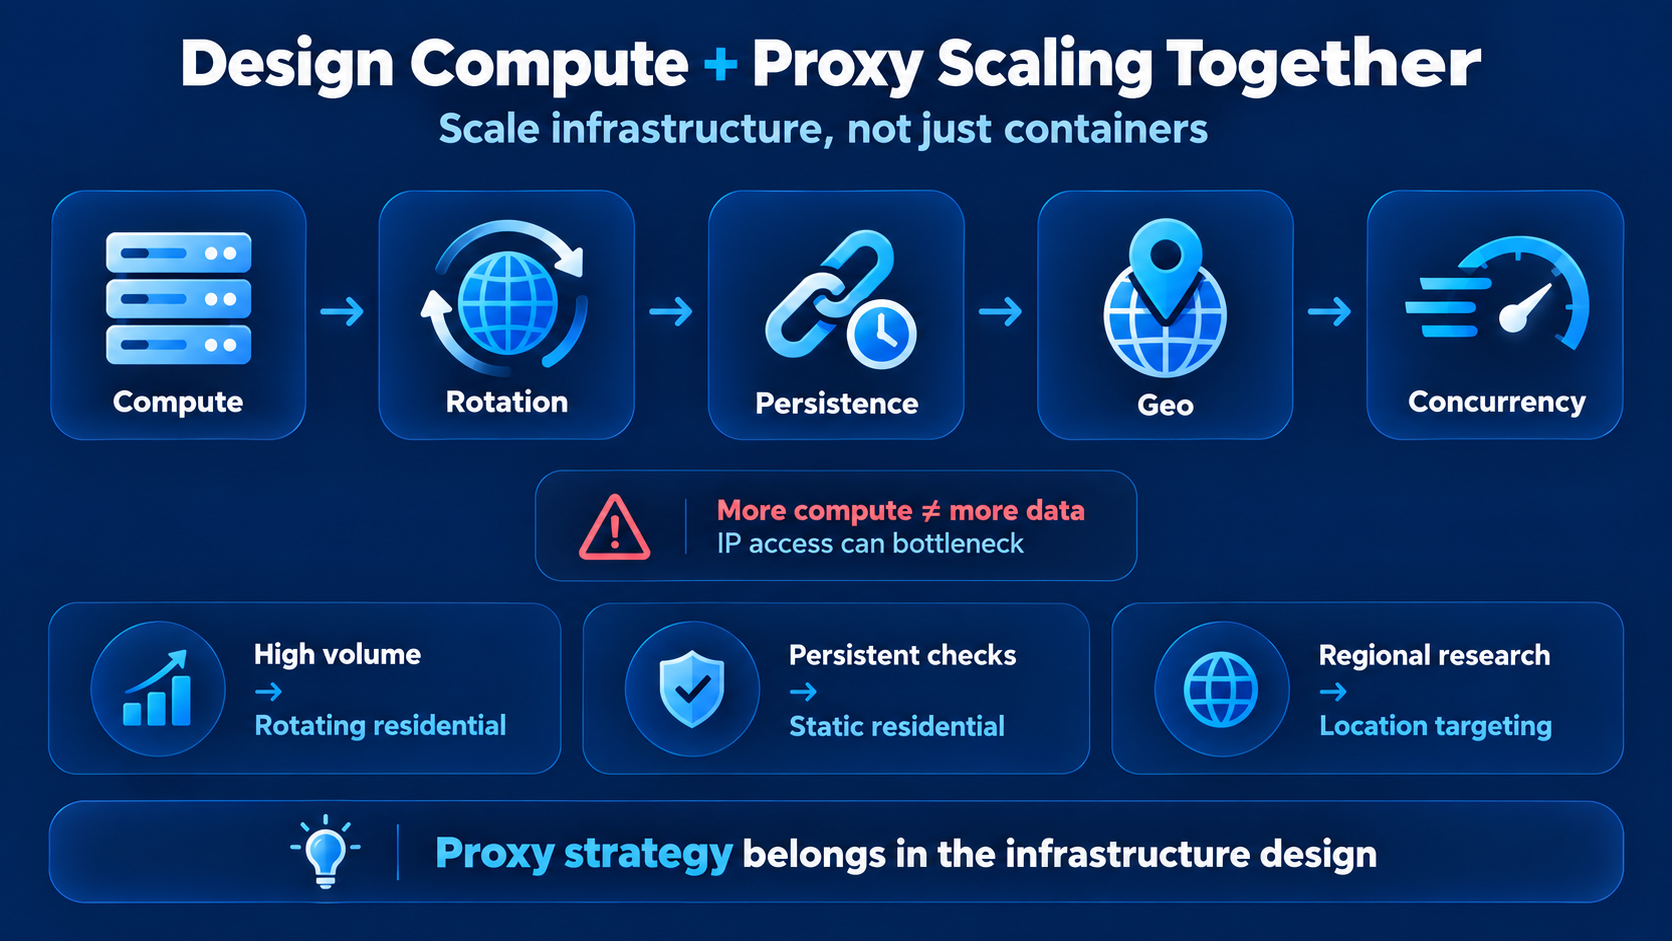
A common mistake in distributed scraping is scaling the computer without scaling network access.
More CPU, memory, or containers will not necessarily produce more usable data if IP access becomes the bottleneck.
A stronger architecture considers several elements together:
- Container capacity
- Proxy rotation
- Session persistence
- Geographic targeting
- Request concurrency
Different workloads require different combinations.
High-volume data collection may favor rotating residential proxies. Persistent verification tasks may require static residential IPs. Regional research may prioritize location targeting.
The proxy strategy should therefore be designed as part of the infrastructure, not added afterward.
Final Thoughts
CaaS gives businesses the flexibility to scale web scraping workloads, but reliable data collection also depends on how those workloads access the web.
A well-designed proxy layer can support IP rotation, session persistence, and location-specific access as scraping operations grow. By integrating SwiftProxy Residential Proxies, Static Residential Proxies, and Web Scraping Proxies into a containerized architecture, teams can build web data pipelines that are more scalable, flexible, and easier to manage.
For modern scraping systems, the strongest results come from designing compute capacity and proxy infrastructure together from the start.
About the author
 Top-tier residential proxy solutions
 {{item.title}}
Related articles

 363


- Please provide your account number, or email address.
- Provide videos or screenshots, and simply describe the problems you are facing.
- Our staff will reply to your message within 24 hours.